
The UX Debt Nobody’s Tracking: Why Your Engineers Think “Working” Means “Done”
Or: Why Your Feature Works Perfectly and Ruins Lives
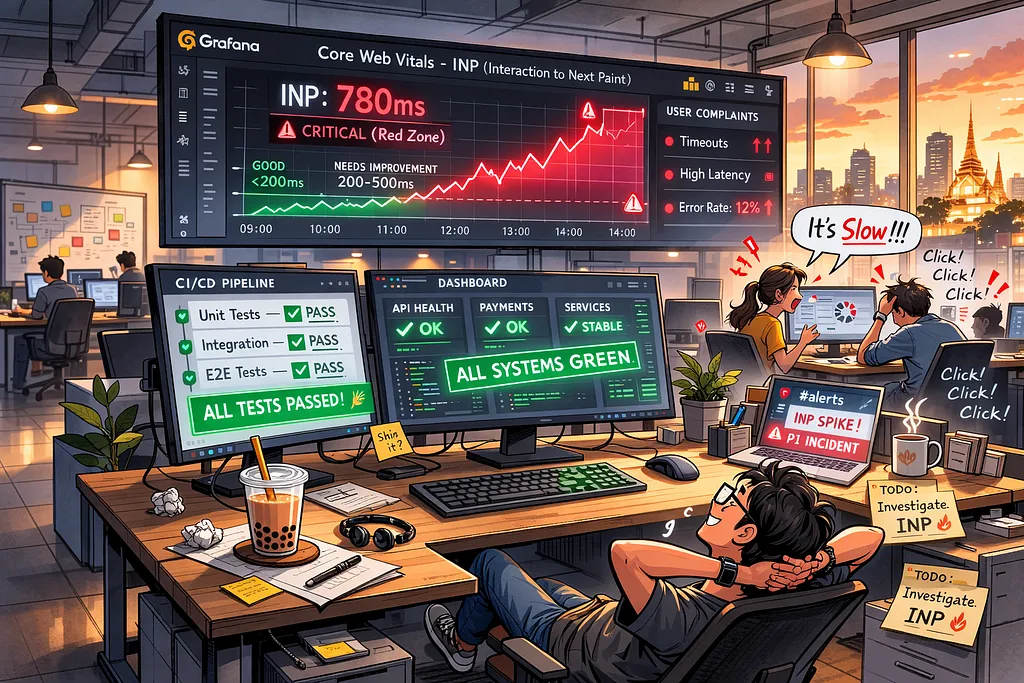
It was 2:14 on a Thursday when Somchai leaned back from his monitor, cracked his knuckles, and said the words that every engineer believes are the end of the story: “It’s working.” The PR had been approved. Tests were green. Monitoring dashboards — all clear. The vinyl floor of our open-plan office on level 22 hummed with the quiet satisfaction of a shipped feature. Three weeks later, customer complaints started trickling into the support channel like condensation down the side of a Thai iced tea — slow, steady, and easy to ignore until you realise your desk is wet.
Nothing was broken. Everything was worse.
We’d built a feature that functioned flawlessly and felt terrible. And because nobody was measuring “feels terrible,” nobody was tracking the debt we’d just shipped to production.
As Maya Angelou observed, “People will forget what you said, people will forget what you did, but people will never forget how you made them feel.” She was talking about human relationships, but she could have been describing your product. Your users don’t remember your clean architecture or your 98% test coverage. They remember that the page froze for a full second when they clicked a table cell. They remember the layout jumping just as they were about to tap “confirm.” They remember the form that technically submitted but left them staring at a screen wondering if anything actually happened.
That feeling — that micro-moment of doubt — is UX debt. And unlike technical debt, almost nobody’s tracking it.
“Working” Is the Wrong Finish Line
Engineers are trained to think in binaries. It compiles or it doesn’t. Tests pass or they fail. The feature ships or it gets rolled back. This binary thinking is what makes us good at our jobs — precision matters when you’re writing code that handles money or routes traffic or processes bookings for millions of users.
But user experience doesn’t live in binaries. It lives on a spectrum, and “working” is just the floor. The gap between “works” and “feels good to use” is where UX debt accumulates, and it compounds silently — each slow interaction, each layout shift, each “technically correct but confusing” flow adds a tiny tax on the user’s patience. No single one of them is a dealbreaker. All of them together are why someone quietly switches to a competitor without ever filing a bug report.
Think about it this way: your CI pipeline doesn’t fail when your Largest Contentful Paint is 4.2 seconds. Your test suite doesn’t catch that your form takes 800 milliseconds to respond to a keystroke. Your code review process can’t detect that the success state is confusing because the loading spinner disappears half a second before the confirmation message appears. “Working” just means the absence of errors, not the presence of quality.
If my Code Entropy post taught us anything, it’s that invisible degradation is the most dangerous kind. The same principle applies here — except instead of your codebase slowly decaying, it’s your user’s patience. And patience, unlike code, doesn’t come with a stack trace when it finally runs out.
The Metrics That Expose UX Debt
Here’s where it gets real. We recently decided to add Interaction to Next Paint — INP — to our list of SLA performance metrics at Agoda. INP measures how quickly your page responds to user interactions: clicks, taps, key presses. Not page load. Not time to first byte. The moment a user does something, how long until the page visually acknowledges it?
Google’s thresholds are clear: under 200 milliseconds at the 75th percentile is “good.” Between 200 and 500 milliseconds “needs improvement.” Above 500 milliseconds is “poor” — red, failing, your page is actively annoying people.
When we applied this metric to one of our greenfield pages, we discovered it was running upwards of one second at P75. One second. Deep in the red. Customers had been complaining, we found out, but nobody had connected the dots because the page worked. It loaded. It displayed data. It was functional.
The problem? The page loaded a substantial amount of data — which isn’t inherently an issue — but used it to render DOM elements that weren’t even visible to the user. And when someone clicked a cell in the table, the entire DOM re-rendered — all of it. Roughly 80% of those DOM nodes weren’t even visible to the user. They were off-screen rows, collapsed sections, data that existed in the page but would never be scrolled to. Every click triggered a re-render of all the data-bound components on the page, not just the cell the user interacted with. The page itself was working fine by every traditional measure. But when users clicked, it took over a second to respond to their action. Not for every user — but enough to show up clearly on the P75.
One second doesn’t sound catastrophic until you consider what happens in the user’s brain during that gap. They click. Nothing happens. They wonder if the click registered. They click again. Now the main thread catches up and processes both clicks, and the UI does something unexpected. The user feels stupid. The user feels frustrated. The user remembers how your product made them feel.
This isn’t hypothetical. When redBus, the Indian bus ticketing platform, optimised their INP — fixing similar issues with excessive re-renders and unthrottled event handlers — they saw a 7% increase in sales. Not from adding features. Not from a redesign. From making the features they already had actually respond when users interacted with them.
Core Web Vitals aren’t abstract Google scores designed to torture SEO teams. They’re emotional proxies. LCP — Largest Contentful Paint — measures “does this feel fast?” CLS — Cumulative Layout Shift — measures “can I trust this page to stay still?” And INP measures something even more fundamental: “does this page respond to me?” When the answer is no — when users click and nothing happens — they don’t think “I bet there’s excessive DOM re-rendering.” They think “is this thing broken?” And they click again, creating more events, more re-renders, more problems. A negative feedback loop that starts with architecture and ends with abandonment.
Why Engineers Miss It (And It’s Not Their Fault)
Before we blame anyone — let’s not. This isn’t a skills problem. It’s a structural one, and there are three reasons it keeps happening.
First, the definition of “done” doesn’t include UX quality. When we defined system ownership at Agoda, we explicitly included “Good Customer Experience (UX, performance etc.)” alongside SLAs for P75 and P90 metrics. That was unusual. Most teams define “done” as code-complete, tests passing, PR merged, deployed to production. Performance targets, when they exist, are about server-side response times. The front-end experience — the thing the customer actually touches — is treated as a nice-to-have rather than a must-have. If your definition of done doesn’t include how the feature feels, you’re institutionalising UX debt in your process.
Second, the feedback loop is broken. Engineers rarely see users interact with what they built. You write code, it gets reviewed, it gets deployed, you move to the next ticket. The people who experience the sluggish table or the shifting layout are thousands of kilometres away, on devices you’ve never tested on, over network connections you’ve never simulated. Without that feedback loop, engineers build to specifications, not to experiences. They match the Figma mock pixel for pixel without ever considering how the interaction flows. This is the solutioneering trap — jumping to implementation before deeply understanding the problem. Except here, the problem isn’t technical. It’s human.
Third, performance degrades gradually. This is Code Entropy applied to the front end. No single PR makes things bad. One developer adds a third-party analytics script. Another introduces a new component that triggers a re-render cascade. Someone adds eager loading for data the user might need eventually. Each change is individually reasonable. Nobody’s watching the trend line. Six months later, your INP has crept from 120 milliseconds to 400, and no one can point to when it happened or whose fault it is, because it’s nobody’s fault. It’s everybody’s fault. It’s the system’s fault.
Making UX Debt Visible
So how do you fix something nobody can see? You make it visible. Same principle as technical debt — if it’s not on the board, it doesn’t exist.
The obvious answer is performance budgets in CI. Set LCP, CLS, and INP thresholds that fail the build, the same way test coverage requirements do. If your INP exceeds 200 milliseconds, the pipeline goes red. Simple, right?
Except it isn’t. If you’re A/B testing — and at Agoda, we A/B test everything — your CI pipeline tests the default variant. The safety fallback is variant A, the control. You never test the change in your pipeline because the change is behind a feature flag that defaults to off. Your synthetic test environment doesn’t know about your experiment. Your lighthouse score looks pristine. Production tells a different story.
What we do instead is put performance metrics into our A/B testing system. This is better for another reason, and it’s one the industry figured out years ago: Real User Monitoring. Yahoo coined the term “RUM” back when they were still relevant, and the principle hasn’t aged a day. In your CI pipeline, you can’t simulate the Akamai POP in Indonesia. You can’t replicate the network conditions of a user in Chiang Mai on a 4G connection during rush hour. Performance is fundamentally end-to-end and dependent on the last mile to the user. Apart from catching obvious regressions, synthetic testing is nearly useless for understanding real-world UX quality. You need real users, on real devices, experiencing real conditions.
So we measure performance metrics — INP, LCP, CLS, the lot — alongside our experiment metrics. If variant B delivers better conversion but degrades INP past our thresholds, that’s a conversation. Not an automatic rejection — a conversation about trade-offs, grounded in data rather than gut feeling.
Beyond measurement, ownership matters. Years ago, we tried the obvious approach: a dedicated performance team. The team that improves the performance. The problem is, if hundreds of other engineers don’t care about performance, that team is just playing a losing game of catch-up — one team fighting against hundreds of others, each of them inadvertently degrading what the performance team just fixed. It’s a losing battle by design.
We still have a performance team, but their role has fundamentally changed. They’re an enabling team now — they provide tools, education, and consultancy. They occasionally build out infrastructure. But they don’t own the performance of your feature. You do. Real User Monitoring dashboards should be owned by the team that builds the feature, not parked in a central platform team’s domain where they become somebody else’s problem. When the team that builds it also owns the performance dashboard for it, accountability becomes natural rather than bureaucratic. Giving ownership to the teams works.
As the Victorian art critic John Ruskin put it, “Quality is never an accident. It is always the result of intelligent effort.” We’ve been treating UX quality as something that should emerge naturally from shipping working features. It doesn’t. Every feature that “works” but degrades the overall feel of the product is proof that quality requires deliberate investment, not just functional correctness.
The Cultural Shift
This isn’t ultimately a tooling problem or a metrics problem. It’s a culture problem. And it comes down to a single question that every engineer and engineering leader should be asking after every deployment: not “does it work?” but “would I want to use this?”
That shift — from functional correctness to experiential quality — is harder than it sounds. It requires engineers to care about things that aren’t in the acceptance criteria. It requires product owners to allocate time for polish that doesn’t show up as a new feature in the release notes. It requires leadership to value quality across all dimensions, not just “tests pass.”
We have a pattern I’ve seen across many organisations: overengineered backends paired with neglected frontends. Teams that will agonise for weeks over the perfect microservice boundary but ship a front-end interaction that re-renders a thousand invisible DOM nodes on every click. The craftsmanship is there — it’s just pointing in the wrong direction.
The fix is ownership that extends past deploy. When your team owns the feature, they own the experience of using that feature. Not just in staging, not just for the P50 user on a fast connection, but for the P75 user on a mid-range device in a market where your competitors are a tap away. We’ve even been debating internally whether P75 is ambitious enough — whether we should be holding ourselves to P90 for LCP, INP, and the rest. Because the users you lose aren’t the ones having the median experience. They’re the ones at the tail end, and that tail is where your reputation gets made.
When engineers only see Figma mocks, they build to pixel specs, not to interaction quality. The handoff needs to include how the thing moves, how it responds, how it feels when the network is slow or the device is struggling. That’s not a design problem or an engineering problem — it’s a product problem, and it needs all three disciplines at the table.
The Bottom Line
UX debt is technical debt’s less visible, more damaging cousin. Technical debt slows down your engineers. UX debt drives away your customers. And while we’ve built an entire vocabulary around identifying, tracking, and paying down technical debt, most organisations don’t even acknowledge that UX debt exists.
Your feature works. Congratulations. Tests pass. Deployment is green. Monitoring shows no errors. And somewhere, a user just clicked a button, watched nothing happen for a second, clicked again in confusion, and is now wondering why the page just did something unexpected. They won’t file a bug report. They’ll just leave. And they’ll remember how your product made them feel.
The next time someone tells you the feature is done because it passes QA, ask them one question: would you want to use it? Not “does it work” — that’s the floor. Does it feel good? Does it respond when you touch it? Does it make you trust it?
If the answer is anything less than yes, you’ve just shipped UX debt. And unlike technical debt, your users are the ones paying the interest.
Now, if you’ll excuse me, I need to go check our INP dashboards. There’s a table on one of our pages that I suspect is re-rendering the entire observable universe every time someone clicks a cell. But hey, the tests pass.